LakeSoul: Cloud-Native Lakehouse Framework
Leading Technical Concept and Architecture
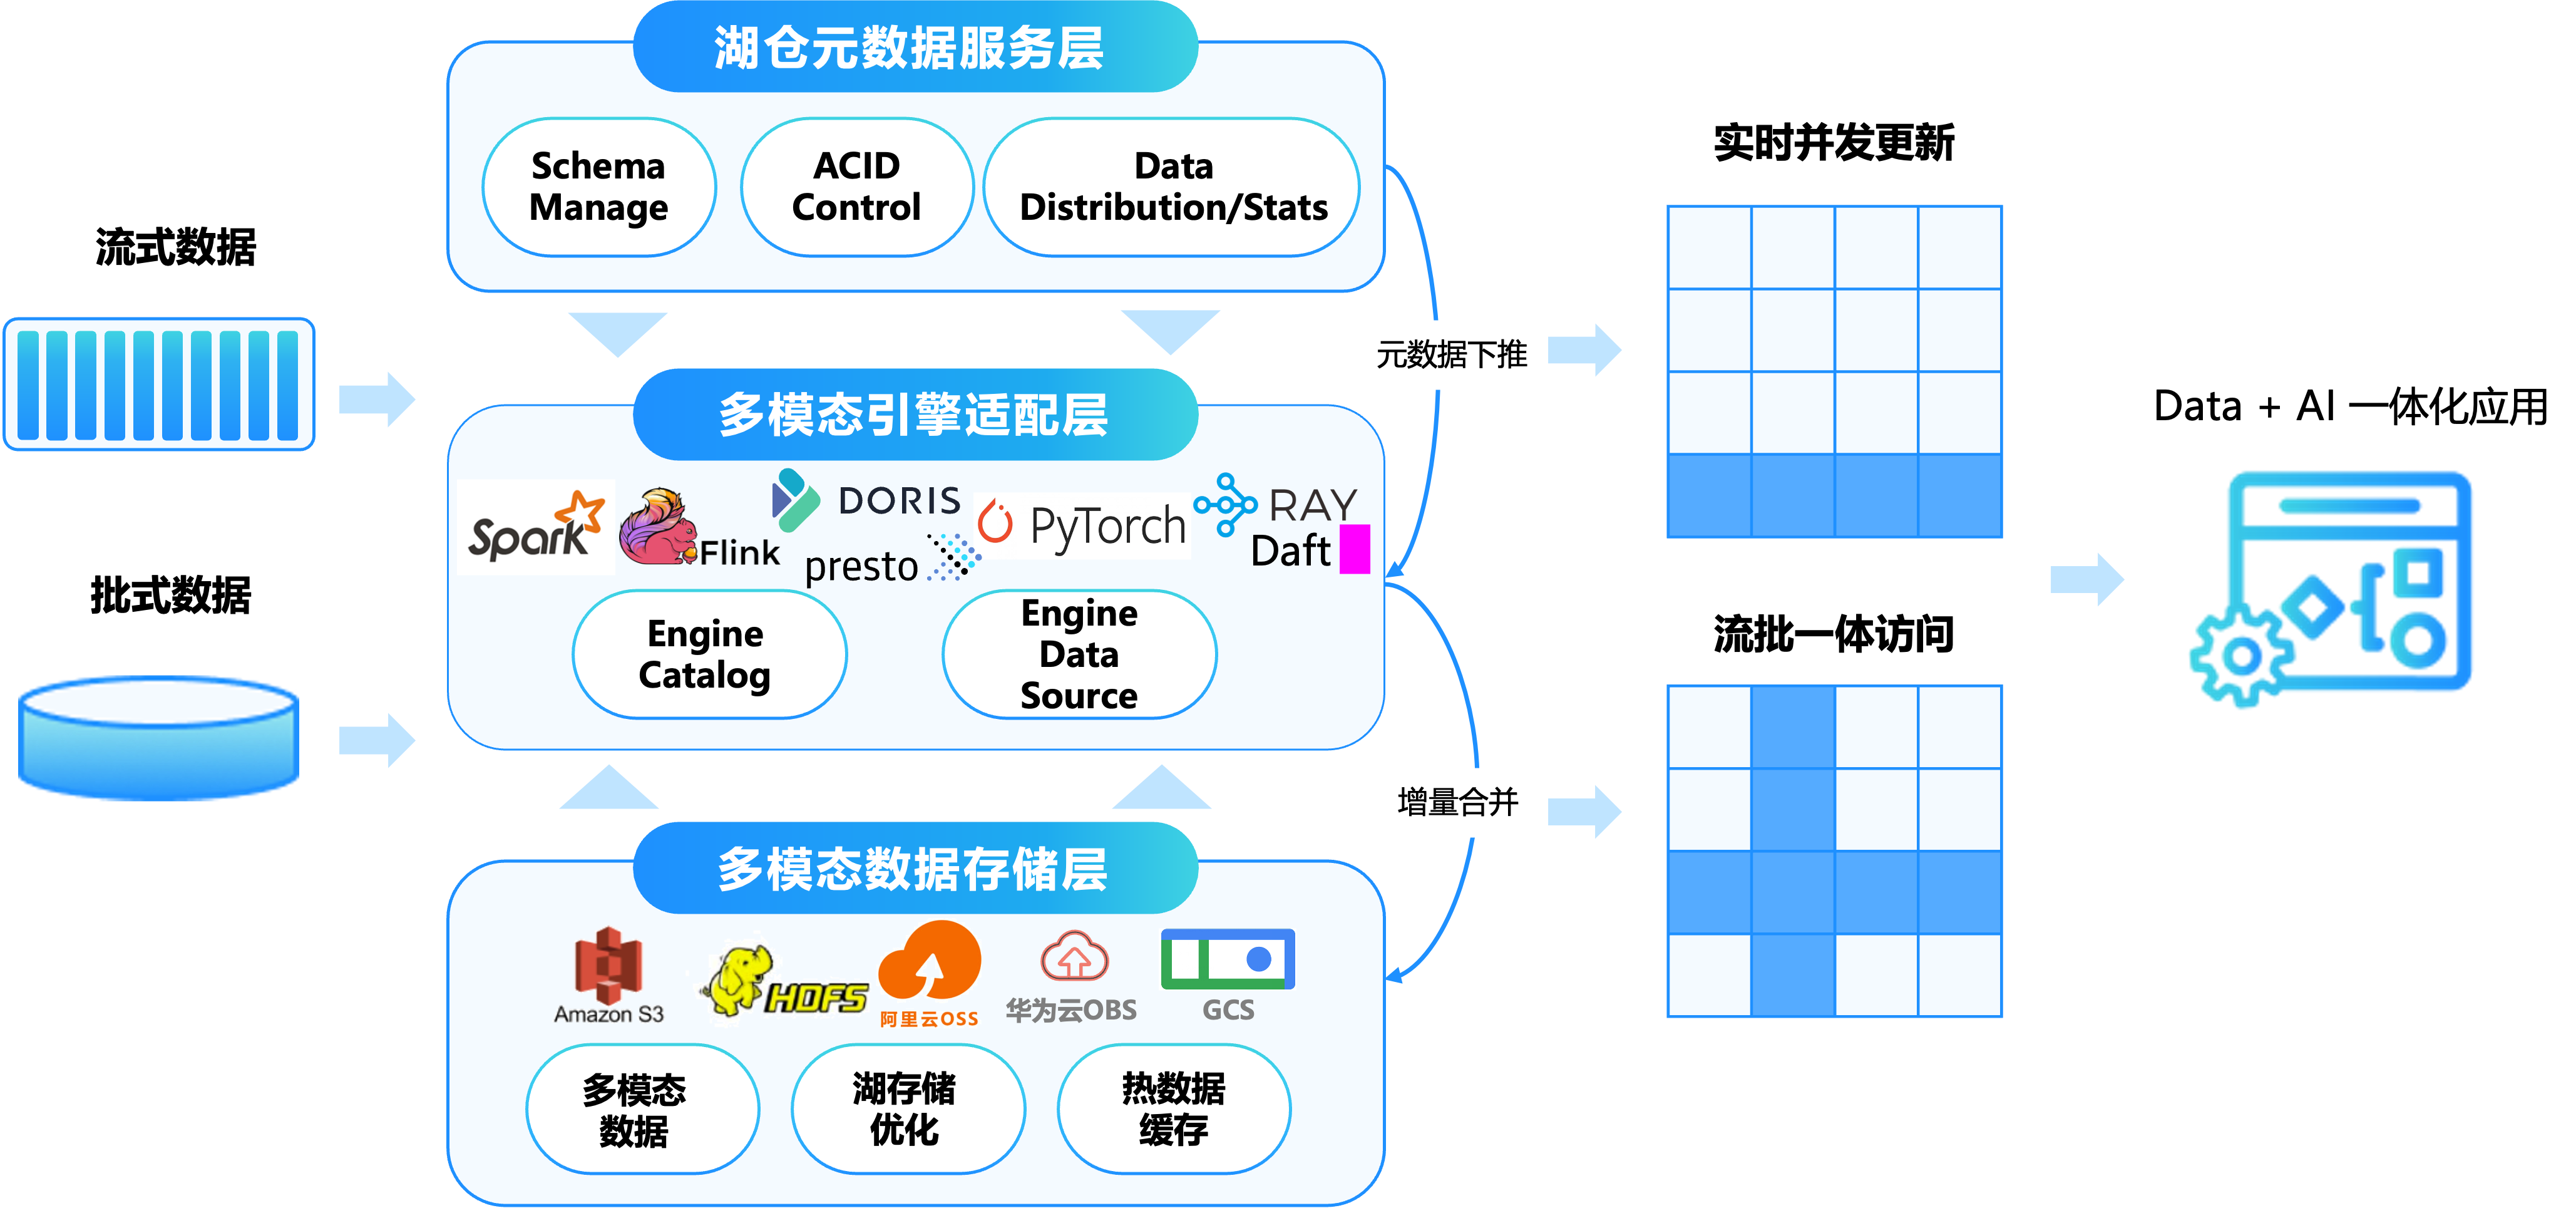
Traditional data architectures struggle with slow response times, high cost, and the inability to unify real-time and batch data at scale. LakeSoul provides a modern lakehouse storage layer that solves these problems, offering high-concurrency, high-throughput read/write capabilities and full warehouse management on the cloud, exposed uniformly to multiple compute engines.
Efficient, Scalable Catalog Metadata Service
Concurrent Writes and ACID Transactions
Incremental Writes and Upserts
Real-Time Lakehouse
Multimodal Fusion Retrieval
Open Ecosystem
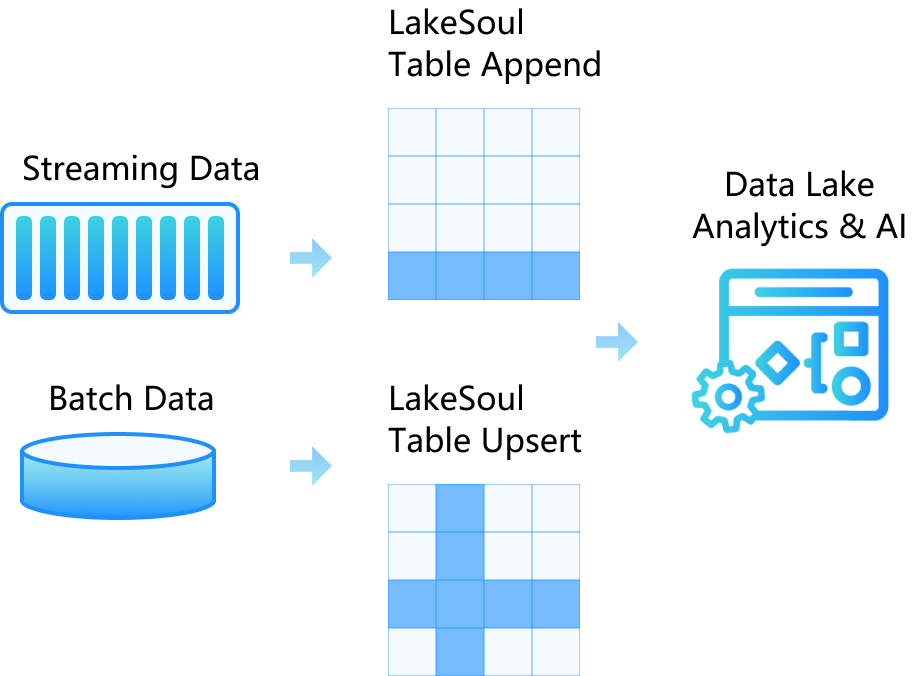
Unified Stream-Batch Table Storage
Rich Application Scenarios That Unlock Business Value
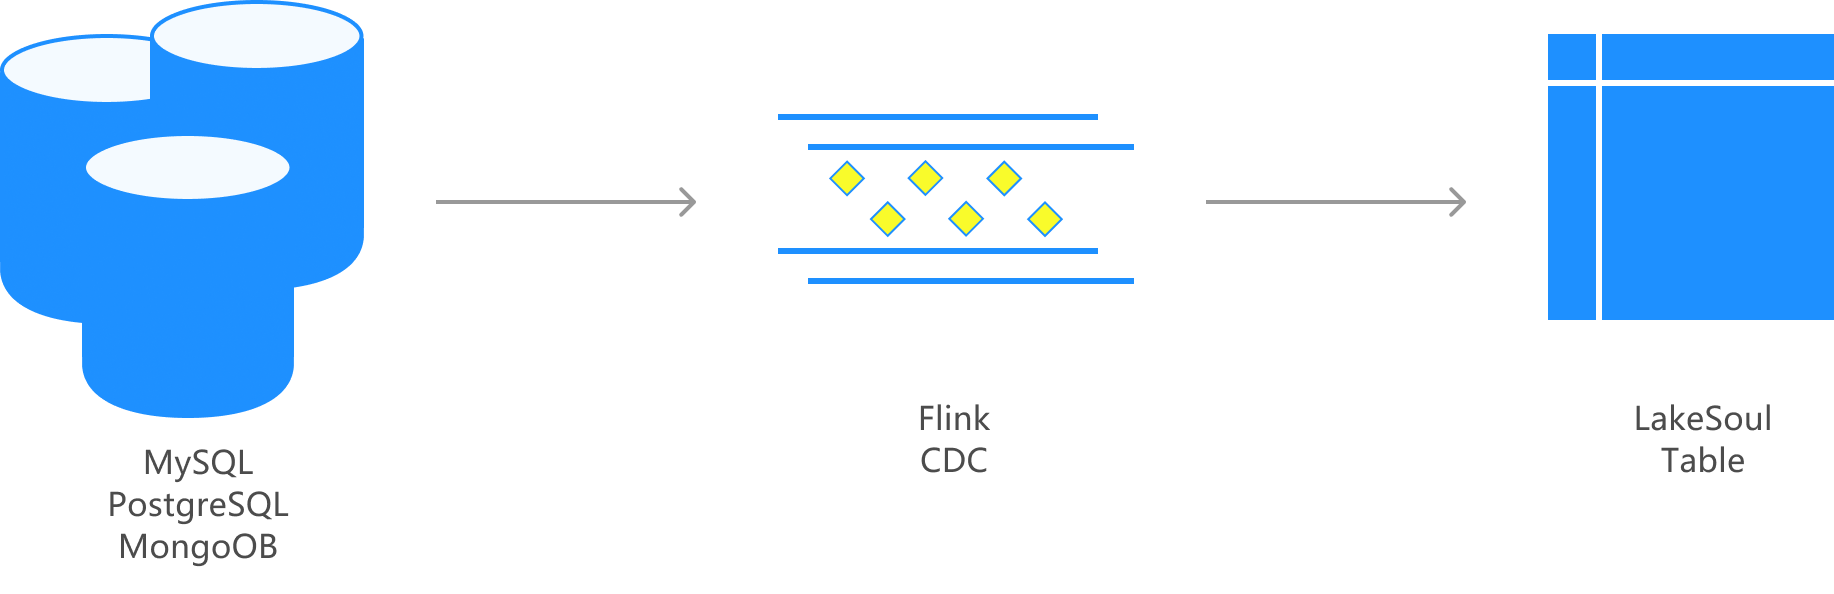
Real-Time Data Ingestion into the Lakehouse
Flink CDC enables real-time ingestion directly from data sources — no T+1 batch imports or Kafka pipelines required
Real-Time Analytics on Operational Databases
With a few configurations for your online data sources, whole-database synchronization and real-time ingestion start automatically. New tables are detected and schema changes are synchronized without manual operations. Operational data is ingested into the lakehouse in real time and flows seamlessly into BI reports and dashboards, so key business metrics are always up to date to support decision-making.
Real-Time Report Analytics
Powered by unified stream-batch updates, data extraction and transformation are done in SQL, simplifying ETL and analytics.
RAG-Powered Intelligent Expert System
LakeSoul provides a native Python interface with support for mainstream AI frameworks such as PyTorch for direct data access, training, and inference. It also supports large-model training and RAG applications


AI Expert Consultation
Join the Community and Share Data Intelligence